
AI integration services: add AI to the product you already have
A new AI feature must not break a product that works, and it must not show users content nobody has checked. We add AI to web and mobile products as a separate AI service that your application calls, and where an error is costly, a person or a test checks the output.
Tell us what you're building.
A few details help us bring the right engineers to the first call.


What an AI integration covers in a product that already works
Three delivered, one in development
Four integrations, four ways AI fits in
Enerace, Centrum Komunikacji and a renovation platform kept running while the AI part was added.
The fourth, Generator ETR for PSONI, is still in development.
Since 2020 we have been building and developing Enerace.Online, an advisory platform for industrial buyers of energy and gas. In its market analysis, news items are pinned to the price charts, and each one gets an AI-generated summary at the moment it is added. The feature has been live since 2025 in a product with more than 20 functional areas in one codebase, and we added it without rewriting the platform. The stack is Python and Django with a GraphQL API, React with TypeScript, React Native, Celery and AWS.
Centrum Komunikacji runs a Polish Sign Language (PJM) interpreting platform, a web and mobile application that we build in a government accessibility program (see the case study). We added live speech-to-text for hard-of-hearing and late-deafened users. A session lasts up to 30 minutes and starts at once when a specialist is free, and the feature has been in production since the platform's launch in April 2026.
We have worked with a product platform in the home renovation and interior furnishing market since 2022. Its AI chat and product-search agent run in a separate AI service that the app calls through a service in its own backend, and a flag at project level (ai_enabled) switches AI on or off without touching the rest of the product.
In Generator ETR for PSONI, an app that turns difficult text into easy-to-read (ETR) language, the phone reads the text from a photo of a letter, on the device itself, with ready-made system libraries (Google ML Kit and Apple Vision). PDF documents take a separate path on the server before they reach the model. The model connection, the text reading and the readability score are in place; the API for other systems is still being built.
The AI part sits outside the application
LLM integration: a separate AI service your app calls
Your backend calls the AI service through its own service layer.
The model sits behind it.
Read more
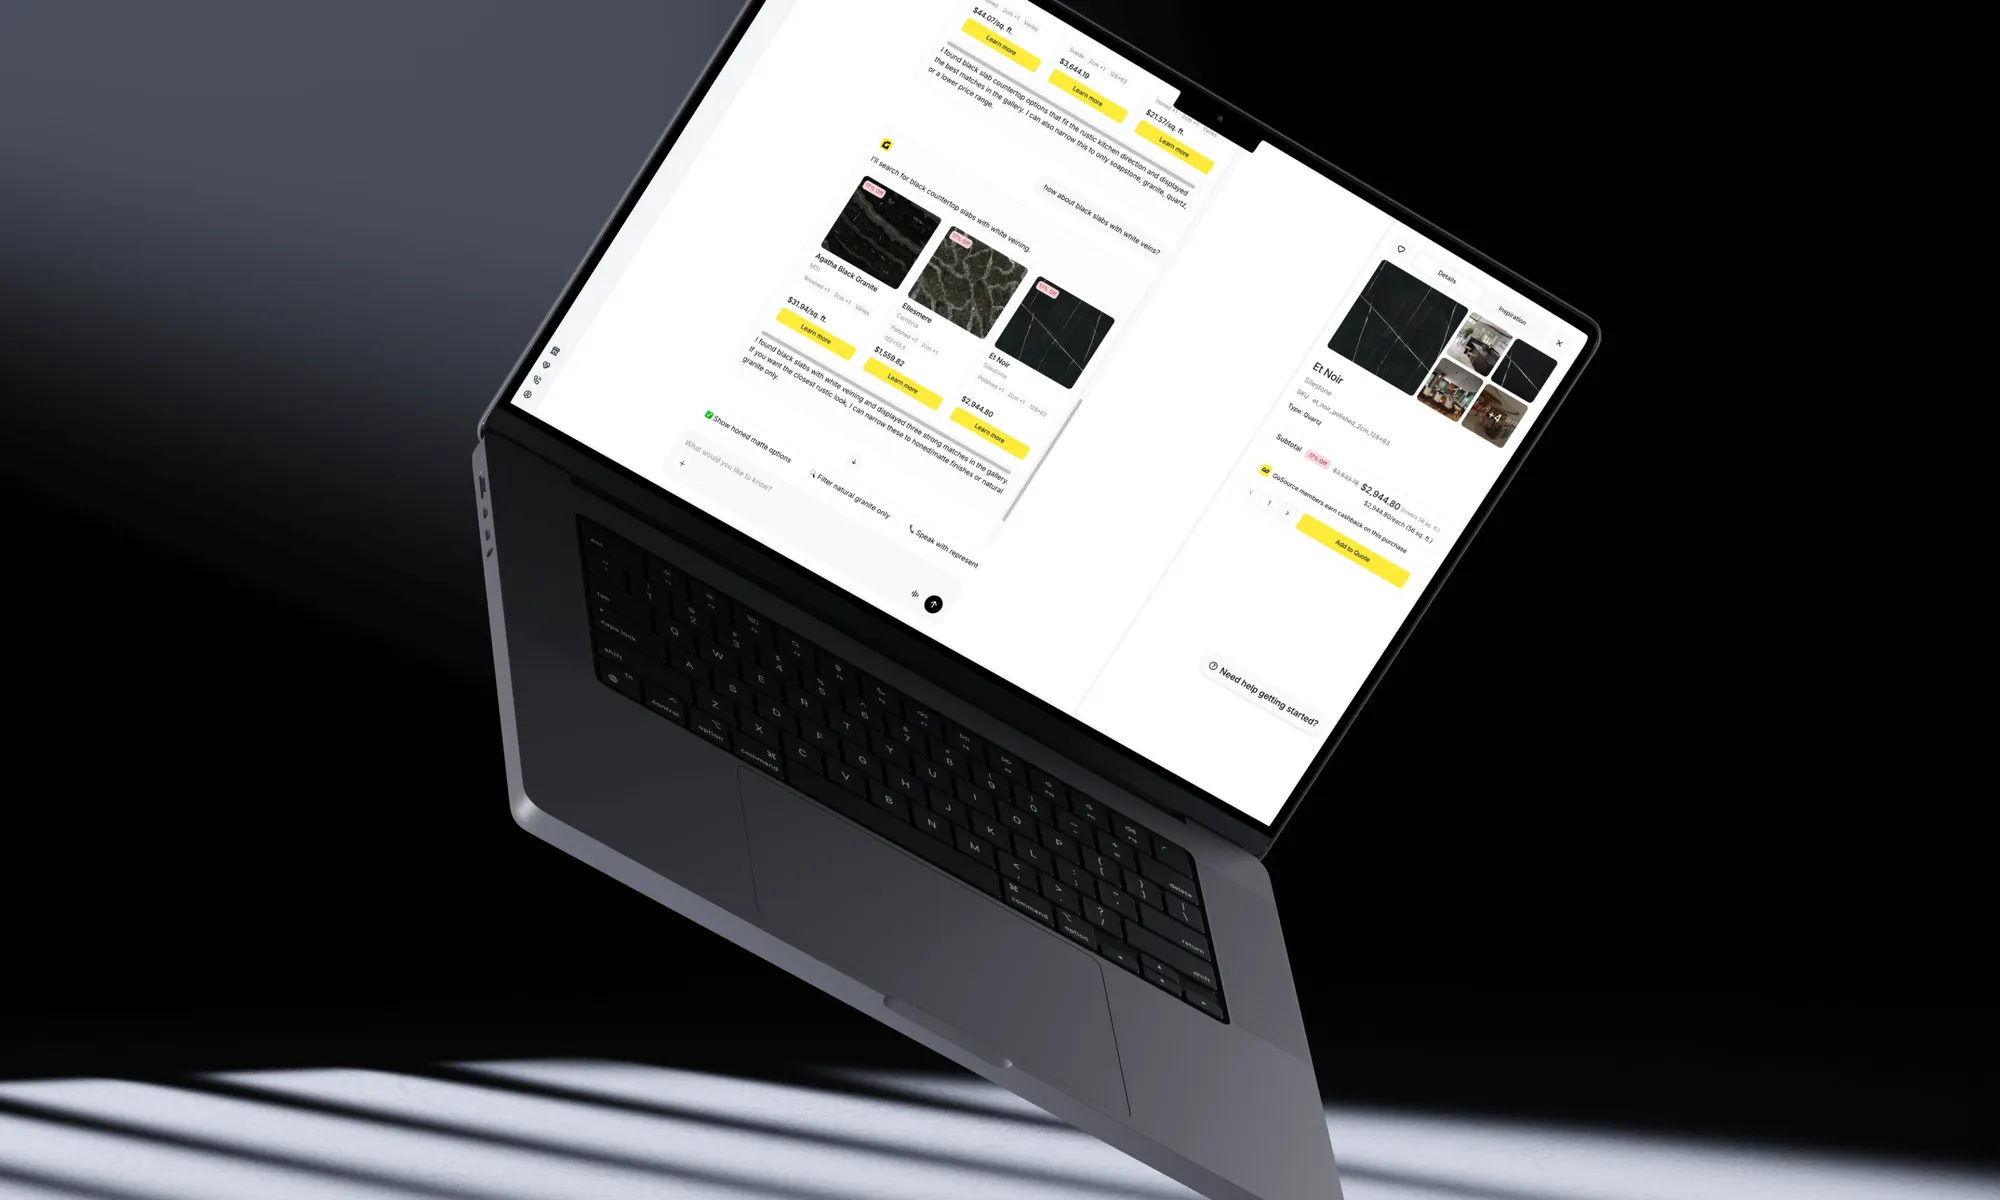
A separate AI service is our default architecture for LLM integration, because the AI part can then be measured, changed or switched off without touching the rest of the product. In Enerace the model is called once, when a news item is added, so the number of calls follows the number of new items, not the number of visits. Which model sits behind the service is a separate choice. A model provider's API is faster to start. When your data cannot leave your infrastructure, we host the model ourselves; see our page on private LLM deployment.
Swapping the model without redeploying the app
In Generator ETR the connection to the model is a setting. An administrator changes the address, key, model name and generation settings in the Django Admin panel, and the backend containers keep running, so a model change needs no new release of the application. The proof of concept started on Gemma 4 and tested PLLuM 12B, a Polish language model, on the same task. Gemma 4 stayed because it gave better results on the project's data, and the same application can run either model through configuration.
Have a product that already works and a task such as answering questions or transcribing speech? Start with a free consultation.
Workflows with a person in them
Where a wrong answer has consequences for users, a person or a test checks the output before anyone relies on it. At Centrum Komunikacji, automatic speech recognition writes a first draft in real time and a transcription specialist corrects it. Only the corrected text reaches the user, as a chat message. Encrypted fields, the option to delete a user's data and an event log protect personal data.
In Enerace an editor approves the summary of each news item. In Generator ETR the checks are the Gunning Fog index, a readability measure, and a reviewer of easy-to-read texts. Jailbreak tests, which try to make the model break its rules, run on every new model iteration.
An API for other systems and an MCP server
Opening the AI feature to other systems
PSONI's AI feature is getting an API for other systems.
AI agents can reach a product through an MCP server.
Read more
The API that PSONI asked for will have four endpoints: logging in with a token, generating an easy-to-read text, listing a user's texts and previewing a historical text, which is kept for 30 days. Access will use an API key from the Django Admin panel, and the endpoints can be switched off later.
To connect AI agents to an existing product, we build an MCP server (Model Context Protocol, a standard that lets AI agents call a product's functions) as a thin layer over its REST API. In our own CMS every MCP tool calls an API endpoint, so validation, permissions and logging stay in the API. Access is per person or per integration and can be revoked at once, and every call is logged. Developers get a Swagger UI and an OpenAPI schema. Agents and chat assistants have their own page, AI agent development, and the server side is covered in MCP server development.
What stays in your hands
Why teams choose us as their AI integration company
You can switch the AI part off, swap its model and see who checks its output, as the projects above show.
The code is yours with each payment, within the scope of use defined in the contract.
Scope, estimate and how a project starts
A free consultation leads to a free basic discovery workshop, one meeting that is also our AI readiness assessment. We use our own AI toolkit in it and look at four things.
- The product: what it does today and where an AI feature would sit in it.
- The data: what the model would read.
- The rules: the legal, security and company constraints your product works under.
- The task and the test: what the AI should do, and which test will show that it works.
Sometimes the result is advice to skip the language model: in a forecasting project we used statistical models instead (see AI MVP development). From the discovery we prepare a basic proof of concept or a mockup that lets us estimate the work; a broader discovery is a separate, larger scope. The estimate covers the whole scope, the simplest solution that meets it, the assumptions and the risks. At the start we agree the method and the communication channels and hold a kick-off with you; on our side the roles are Project Tech Leader, Product Owner and Scrum Master. After launch we stay on for support and maintenance, because models, prompts and the data they read keep changing.
Do you have questions?
AI integration services: frequently asked questions
-
The AI part, the choice of model, checks on the output and support after launch, all after a free discovery workshop.
-
A team that builds the product and integrates the model. We did it for Enerace and Centrum Komunikacji, and we start with a free discovery workshop that settles the scope.
-
The LLM part is a separate service that your backend calls, so the product around it is not rewritten. Enerace is the example: AI summaries were added next to more than 20 functional areas.
-
Yes. In Generator ETR the model is a setting, not code, so changing it needs no new release.
-
Yes. On the renovation platform a project-level flag does it, and nothing else in the product changes.
-
It depends on where your data may go. A provider's API is faster to start; when the data cannot leave your infrastructure, we host the model. We decide it with you in discovery.
-
A person or a test, depending on what an error costs: a specialist, an editor, a readability score or jailbreak tests.
-
Not always. We say so in discovery when a simpler approach fits the task better.
-
Discovery comes first and is free. The estimate then covers the whole scope, the simplest solution that meets it, the assumptions and the risks, and the project starts with a kick-off with you.
-
Yes. We settle the scope and architecture of a RAG system in the discovery workshop. We do not describe RAG projects here because they are covered by NDA.
-
You do. Copyright passes to you with each payment, within the scope of use defined in the contract.
AI features added to products that already work.
Your message goes to
Filip Szamborski
Co-founder & CEO

Your message goes to
Karol Oponowicz
Co-founder & Business Owner
Your message goes to
Paweł Zieliński
Co-founder & Business Owner
SO FAR WE HAVE WORKED WITH BRANDS LIKE:
Thank you for your message.
We read every message ourselves and get back to you within 48 hrs on business days.
Something urgent? hello@ordergroup.co